language models
Language models use the concept of an embedding, a numerical vector computed from a piece of text by a model trained on large collections of text, to convert the text in a dataset into vectors that can be compared with cosine distance and examined with PCA, and generative models use the same approach to produce new text from a prompt. This analysis can be used to answer questions such as “Which publication titles in this set have the most similar embeddings?”, “Do these odor descriptions separate along the first principal components of their embeddings?”, or “What tags does the generative model assign to each abstract?”
Much of the information in science is written rather than measured: paper titles and abstracts, odor descriptions, notes on samples. Earlier chapters analyzed numerical data, and language models are how text joins those analyses. Language models are algorithms trained on large amounts of text, and in this chapter we focus on embedding models, which convert each piece of text into an embedding: a vector of numbers that captures its essential features, so that texts with similar meanings end up with similar vectors. Once text is in that form, the techniques we have already covered apply to it directly. Here we use PCA to see which publication titles from a PubMed search, or which odor descriptions, group together, and because embeddings are compared by direction rather than size, cosine distance (from the distances and scaling chapter) is the usual way to measure how alike two of them are. The chapter closes with generative models, which build on the same machinery to write new text, such as tags summarizing each abstract. The next chapter applies the embedding idea to protein sequences.
To run the analyses in this chapter, you will need three things.
- Please ensure that your computer can run the following R script. It may prompt you to install additional R packages.
source("https://thebustalab.github.io/phylochemistry/modules/language_model_analysis.R")
## Loading language model module...
## Loading dgx module...
## Done with dgx loading!
## Done with language model loading!- Please create an account and obtain an API key at https://pubmed.ncbi.nlm.nih.gov/ (Login > Account Settings > API Key Management), then store it as described just below.
- Please set up your class tokens for the course language model endpoints, following the setting up your class tokens section below.
Your PubMed API key and your class tokens are long sequences of numbers and letters, like passwords. Keep them handy, and keep them private.
A basic form of an embedding model is a neural network called an autoencoder. Autoencoders consist of two main parts: an encoder and a decoder. The encoder takes the input data and compresses it into a lower-dimensional representation, called an embedding. The decoder then reconstructs the original input from this embedding, and the output from the decoder is compared against the original input. The model (the encoder and the decoder) is then iteratively optimized with the objective of minimizing a loss function that measures the difference between the original input and its reconstruction, resulting in an embedding model that creates meaningful embeddings that capture the important aspects of the original input.
setting up your class tokens
The embedding and text generation models used in this chapter are served by the course’s own endpoints, so you do not need a Hugging Face account or any commercial API key of your own. What you do need is a token for each endpoint. Both tokens are posted on the course Canvas page. Treat them exactly like passwords: do not type them into your scripts, do not share them outside the class, and never commit them to GitHub. Your own PubMed key from step 2 above gets stored in the same place, and deserves the same care.
Rather than putting any of these in your code, you will store them in a file that R reads automatically when it starts up, called .Renviron, which lives in your home directory. Open it by running:
file.edit("~/.Renviron")That will open an editor (the file may well be empty, or may not exist yet, and that is fine). Add the following five lines, replacing each paste_..._here with the matching value (the two class tokens from Canvas, and your own PubMed key), then save the file:
EMBED_SERVER_URL=https://embed.lbusta.org
EMBED_SERVER_TOKEN=paste_the_embedding_token_here
GENERATE_SERVER_URL=https://generate.lbusta.org
GENERATE_SERVER_TOKEN=paste_the_generation_token_here
PUBMED_TOKEN=paste_your_own_pubmed_key_here
Now restart R, because .Renviron is only read when R starts (in RStudio: Session > Restart R). Once R has restarted, check that it can see your settings:
Sys.getenv("EMBED_SERVER_URL")If that prints the address of the embedding endpoint, you are ready to go. If it prints an empty string "", then R is not seeing the file. Make sure you saved .Renviron, that it is in your home directory, and that you restarted R afterwards.
With those variables set, embedText() and generateText() will send their requests to the course endpoints automatically, and searchPubMed() will pick up your key with Sys.getenv("PUBMED_TOKEN"). You will notice that no actual key or token appears anywhere in the code in this chapter, which is exactly the point: secrets belong in your environment, not in your analysis scripts.
pre-reading
Please read over the following:
- Text Embeddings: Comprehensive Guide. In her article, “Text Embeddings: Comprehensive Guide”, Mariya Mansurova explores the evolution, applications, and visualization of text embeddings. Beginning with early methods like Bag of Words and TF-IDF, she traces how embeddings have advanced to capture semantic meaning, highlighting significant milestones such as word2vec and transformer-based models like BERT and Sentence-BERT. Mansurova explains how these embeddings transform text into vectors that computers can analyze for tasks like clustering, classification, and anomaly detection. She provides practical examples using tools like OpenAI’s embedding models and dimensionality reduction techniques, making this article an in-depth resource for both theoretical and hands-on understanding of text embeddings.
text embeddings
Here, we will create text embeddings using publication data from PubMed. Text embeddings are numerical representations of text that preserve important information and allow us to apply mathematical and statistical analyses to textual data. Below, we use a series of functions to obtain titles and abstracts from PubMed, create embeddings for their titles, and analyze them using principal component analysis.
First, we use the searchPubMed function to extract relevant publications from PubMed based on specific search terms. This function interacts with the PubMed website via a tool called an API. An API, or Application Programming Interface, is a set of rules that allows different software programs to communicate with each other. In this case, the API allows our code to access data from the PubMed database directly, without needing to manually search through the website. An API key is a unique identifier that authenticates a user when using an API. It acts like a password, granting permission to access the API services. Obtaining one requires signing up for an NCBI account at https://pubmed.ncbi.nlm.nih.gov/. Here, rather than typing the key into the code, we read it out of the environment with Sys.getenv("PUBMED_TOKEN"), using the same .Renviron file set up at the start of this chapter. Pass it to the searchPubMed function along with the search terms. Here we use “beta-amyrin synthase,” “friedelin synthase,” “Sorghum bicolor,” and “cuticular wax biosynthesis.” We also specify that the results should be sorted according to relevance (as opposed to sorting by date) and that only three results per term (the top three most relevant hits) should be returned:
search_results <- searchPubMed(
  search_terms = c("beta-amyrin synthase", "friedelin synthase", "sorghum bicolor", "cuticular wax biosynthesis"),
  pubmed_api_key = Sys.getenv("PUBMED_TOKEN"),
  retmax_per_term = 3,
  sort = "relevance"
)
colnames(search_results)
## [1] "entry_number" "term"         "date"
## [4] "journal"      "title"        "doi"
## [7] "abstract"
select(search_results, term, title)
## # A tibble: 12 × 2
##    term                       title
##    <chr>                      <chr>
##  1 beta-amyrin synthase       Ginsenosides in Panax genus a…
##  2 beta-amyrin synthase       β-Amyrin synthase from Conyza…
##  3 beta-amyrin synthase       [Cloning and bioinformatics a…
##  4 friedelin synthase         Friedelin in Maytenus ilicifo…
##  5 friedelin synthase         Genome Mining and Gene Expres…
##  6 friedelin synthase         The Methionine 549 and Leucin…
##  7 sorghum bicolor            Current status and prospects …
##  8 sorghum bicolor            Sorghum (Sorghum bicolor).
##  9 sorghum bicolor            Potential food applications o…
## 10 cuticular wax biosynthesis Regulatory mechanisms underly…
## 11 cuticular wax biosynthesis Cuticular wax in wheat: biosy…
## 12 cuticular wax biosynthesis Update on Cuticular Wax Biosy…
The output here shows that we’ve retrieved records for various publications, each containing information such as the title, journal, and search term used. This gives us a dataset that we can further analyze to gain insights into the relationships between different research topics.
GloVe embeddings
GloVe (Global Vectors) embeddings represent words as fixed numeric vectors based on how often words co-occur across a large text corpus. In practice, GloVe learns a vector for each word so that words that appear in similar contexts end up with similar vectors. This means each word has a single embedding that does not change across sentences.
At the word level, each token is replaced by its corresponding vector from the GloVe table. At the sentence level, these word vectors are combined into a single vector that represents the whole sentence. A simple approach is to average the word vectors across the sentence (other approaches include weighted averages or more complex pooling).
Below, we generate sentence-level GloVe embeddings for the PubMed titles retrieved in this chapter. This uses the same PubMed results as the analysis below, but switches the embedding method to GloVe by providing a local GloVe file path. Download a GloVe file from https://nlp.stanford.edu/projects/glove/, then record where you put it in your .Renviron file as GLOVE_FILE, alongside the tokens you stored at the start of this chapter. The code below reads that setting with Sys.getenv(), so the file itself can live anywhere on your machine.
search_results_glove <- embedText(
  search_results,
  column_name = "title",
  path_to_glove_file = Sys.getenv("GLOVE_FILE")
)
##
  |
  |                                                  |   0%
  |
  |====                                              |   8%
  |
  |========                                          |  17%
  |
  |============                                      |  25%
  |
  |=================                                 |  33%
  |
  |=====================                             |  42%
  |
  |=========================                         |  50%
  |
  |=============================                     |  58%
  |
  |=================================                 |  67%
  |
  |======================================            |  75%
  |
  |==========================================        |  83%
  |
  |==============================================    |  92%
  |
  |==================================================| 100%

runMatrixAnalysis(
  data = search_results_glove,
  analysis = "pca",
  columns_w_values_for_single_analyte = colnames(search_results_glove)[grep("embed", colnames(search_results_glove))],
  columns_w_sample_ID_info = c("title", "term")
) %>%
  ggplot() +
    geom_point(aes(x = Dim_1, y = Dim_2, fill = term), shape = 21, color = "black", size = 5) +
    geom_mark_ellipse(aes(x = Dim_1, y = Dim_2, fill = term), color = "black") +
    theme_minimal() +
    scale_fill_manual(values = c("maroon", "gold", "steelblue", "darkgreen"))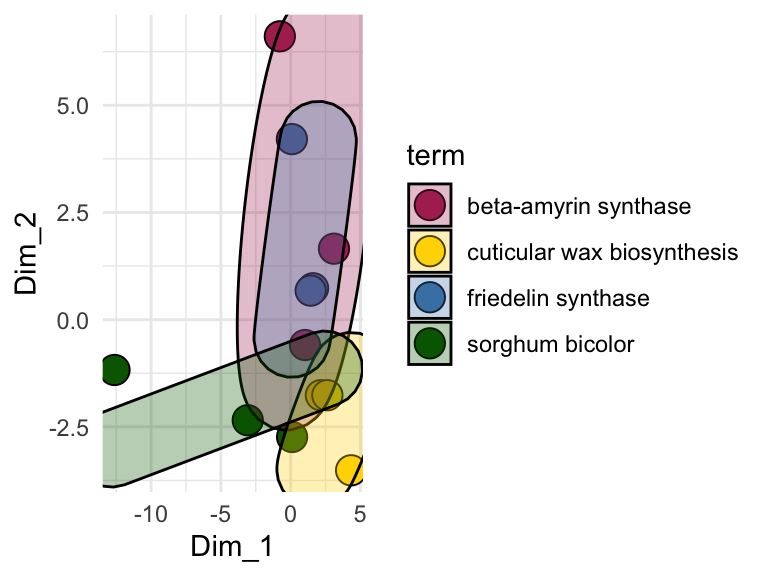
transformer embeddings
Transformer embeddings start with a vector for each word, then update those vectors by looking at how each word relates to the other words in the sentence. In very simple terms, the model lets each word “pay attention” to the others and adjusts its vector based on that context. This creates contextual embeddings, where the same word can end up with different vectors depending on the sentence it appears in.
Below, we generate transformer-based embeddings using the course embedding endpoint. This example uses the existing PubMed results and embeds the titles with a pretrained transformer model.
Next, we use the embedText function to create embeddings for the titles of the extracted publications. Unlike PubMed, this does not need a personal API key: the request is authenticated with the class token placed in the .Renviron file above, and embedText() picks that up on its own.
To set up the embedText function, provide the dataset containing the text to be embedded (in this case, search_results, the output from the PubMed search above) and the column with the text (title). That is all it needs. The embeddings are generated using a pre-trained embedding language model called ‘BAAI/bge-small-en-v1.5’, which runs on the course server. This model is designed to create compact, informative numerical representations of text, making it suitable for a wide range of downstream tasks, such as clustering or similarity analysis. For more about the model and its capabilities, its documentation is at https://huggingface.co/BAAI/bge-small-en-v1.5.
search_results_embedded <- embedText(
  df = search_results,
  column_name = "title"
)
##
  |
  |                                                  |   0%
  |
  |==================================================| 100%
search_results_embedded[1:3,1:10]
## # A tibble: 3 × 10
##   entry_number term  date       journal title doi   abstract
##          <dbl> <chr> <date>     <chr>   <chr> <chr> <chr>
## 1            1 beta… 2024-04-03 Acta p… Gins… 10.1… Ginseno…
## 2            2 beta… 2019-11-20 FEBS o… β-Am… 10.1… Conyza …
## 3            3 beta… 2022-09-28 Zhongg… [Clo… 10.1… Dipsaci…
## # ℹ 3 more variables: embedding_1 <dbl>, embedding_2 <dbl>,
## #   embedding_3 <dbl>
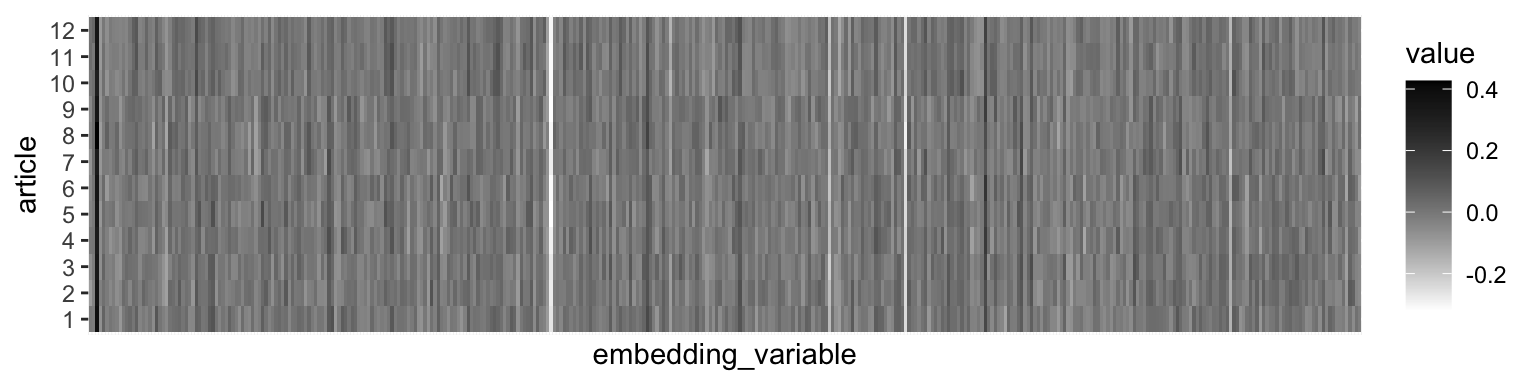
The output of the embedText function is a data frame where the 384 appended columns represent the embedding variables. These embeddings capture the features of each publication title. These embeddings are like bar codes:
search_results_embedded %>%
  pivot_longer(
    cols = grep("embed",colnames(search_results_embedded)),
    names_to = "embedding_variable",
    values_to = "value"
  ) %>%
  ggplot() +
    geom_tile(aes(x = embedding_variable, y = factor(entry_number), fill = value)) +
    scale_y_discrete(name = "article") +
    scale_fill_gradient(low = "white", high = "black") +
    theme(
      axis.text.x = element_blank(),
      axis.ticks.x = element_blank()
    )
To examine the relationships between the publication titles, we perform PCA on the text embeddings. We use the runMatrixAnalysis function, specifying PCA as the analysis type and indicating which columns contain the embedding values. We visualize the results using a scatter plot, with each point representing a publication title, colored by the search term it corresponds to. The grep function is used here to search for all column names in the search_results data frame that contain the word ‘embed’. This identifies and selects the columns that hold the embedding values, which will be used as the columns with values for single analytes for the PCA and enable the visualization below. While we’ve seen lots of PCA plots over the course of our explorations, note that this one is different in that it represents the relationships between the meaning of text passages (!) as opposed to relationships between samples for which we have made many measurements of numerical attributes.
runMatrixAnalysis(
  data = search_results_embedded,
  analysis = "pca",
  columns_w_values_for_single_analyte = colnames(search_results_embedded)[grep("embed", colnames(search_results_embedded))],
  columns_w_sample_ID_info = c("title", "journal", "term")
) %>%
  ggplot() +
    geom_label_repel(
      aes(x = Dim_1, y = Dim_2, label = str_wrap(title, width = 35)),
      size = 2, min.segment.length = 0.5, force = 50
    ) +
    geom_point(aes(x = Dim_1, y = Dim_2, fill = term), shape = 21, size = 5, alpha = 0.7) +
    scale_fill_brewer(palette = "Set1") +
    scale_x_continuous(expand = c(0,1)) +
    scale_y_continuous(expand = c(0,5)) +
    theme_minimal()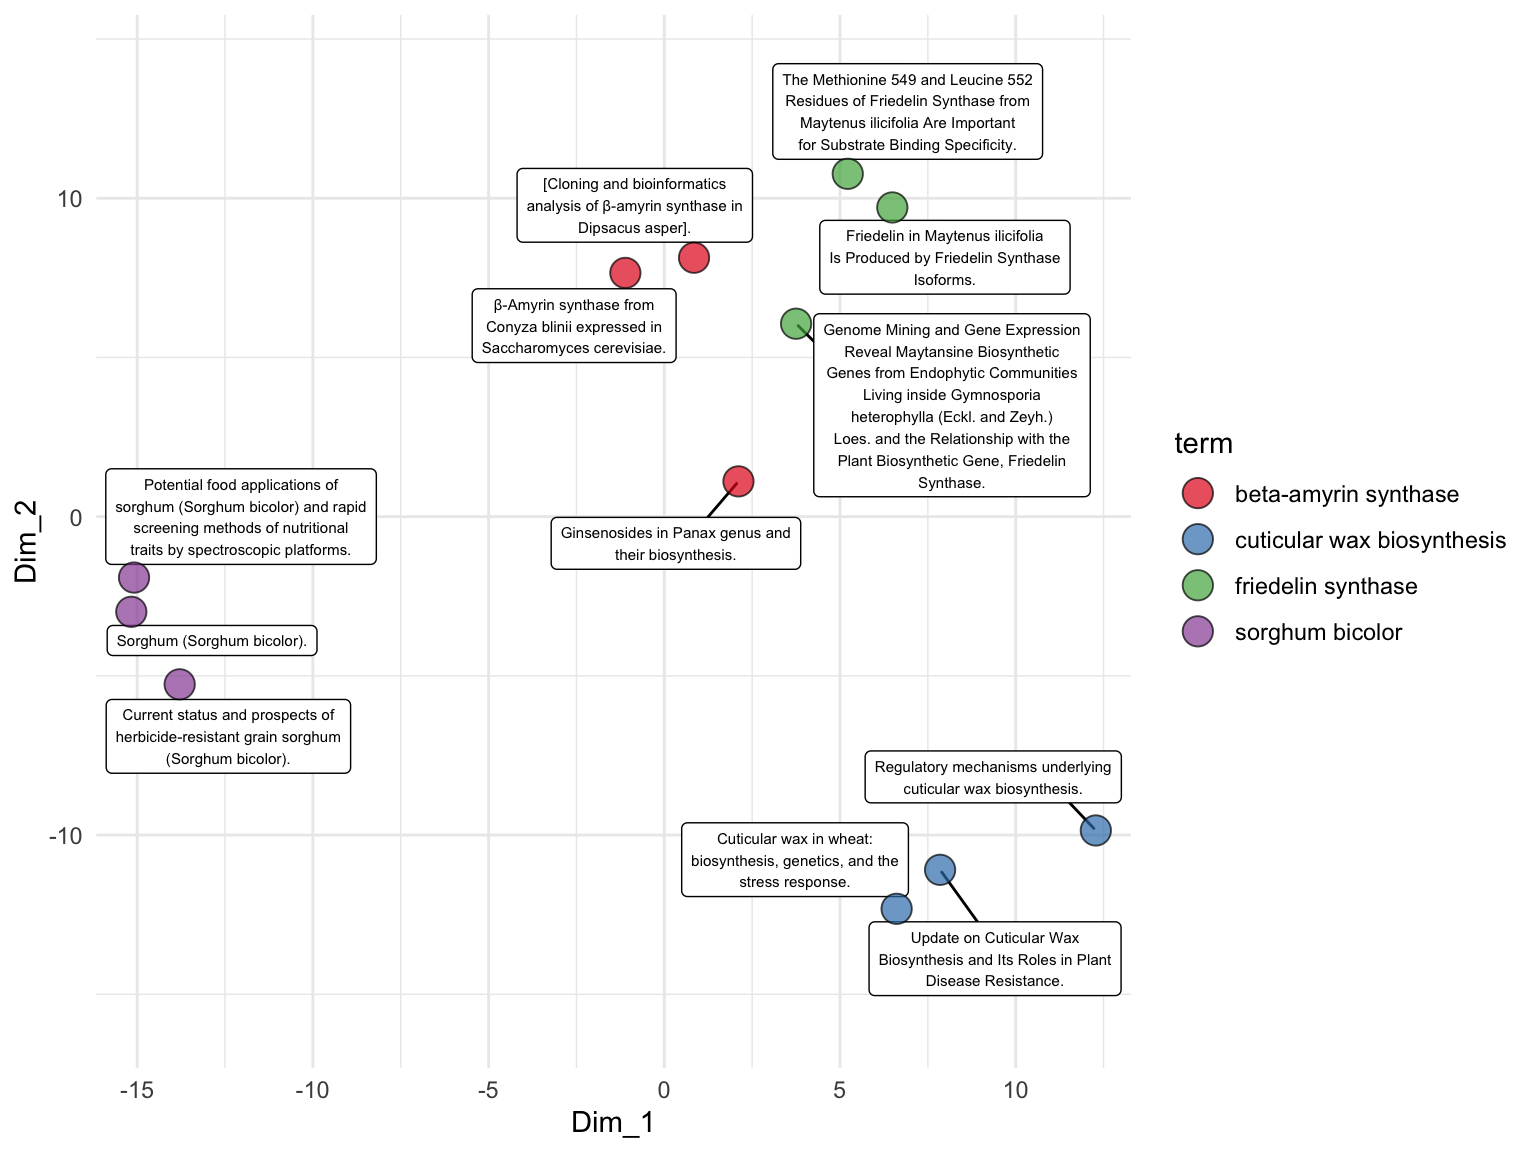
We can also use embeddings to examine data that are not full sentences but rather just lists of terms, such as the descriptions of odors in the beer_components dataset:
n <- 31

odor <- data.frame(
  sample = seq(1,n,1),
  odor = dropNA(unique(beer_components$analyte_odor))[sample(1:96, n)]
)

out <- embedText(
  odor, column_name = "odor"
)
##
  |
  |                                                  |   0%
  |
  |=========================                         |  50%
  |
  |==================================================| 100%

runMatrixAnalysis(
  data = out,
  analysis = "pca",
  columns_w_values_for_single_analyte = colnames(out)[grep("embed", colnames(out))],
  columns_w_sample_ID_info = c("sample", "odor")
) -> pca_out

pca_out$color <- rgb(
  scales::rescale(pca_out$Dim_1, to = c(0, 1)),
  0,
  scales::rescale(pca_out$Dim_2, to = c(0, 1))
)

ggplot(pca_out) +
  geom_label_repel(
    aes(x = Dim_1, y = Dim_2, label = str_wrap(odor, width = 35)),
    size = 2, min.segment.length = 0.5, force = 25
  ) +
  geom_point(aes(x = Dim_1, y = Dim_2), fill = pca_out$color, shape = 21, size = 3, alpha = 0.7) +
  theme_minimal()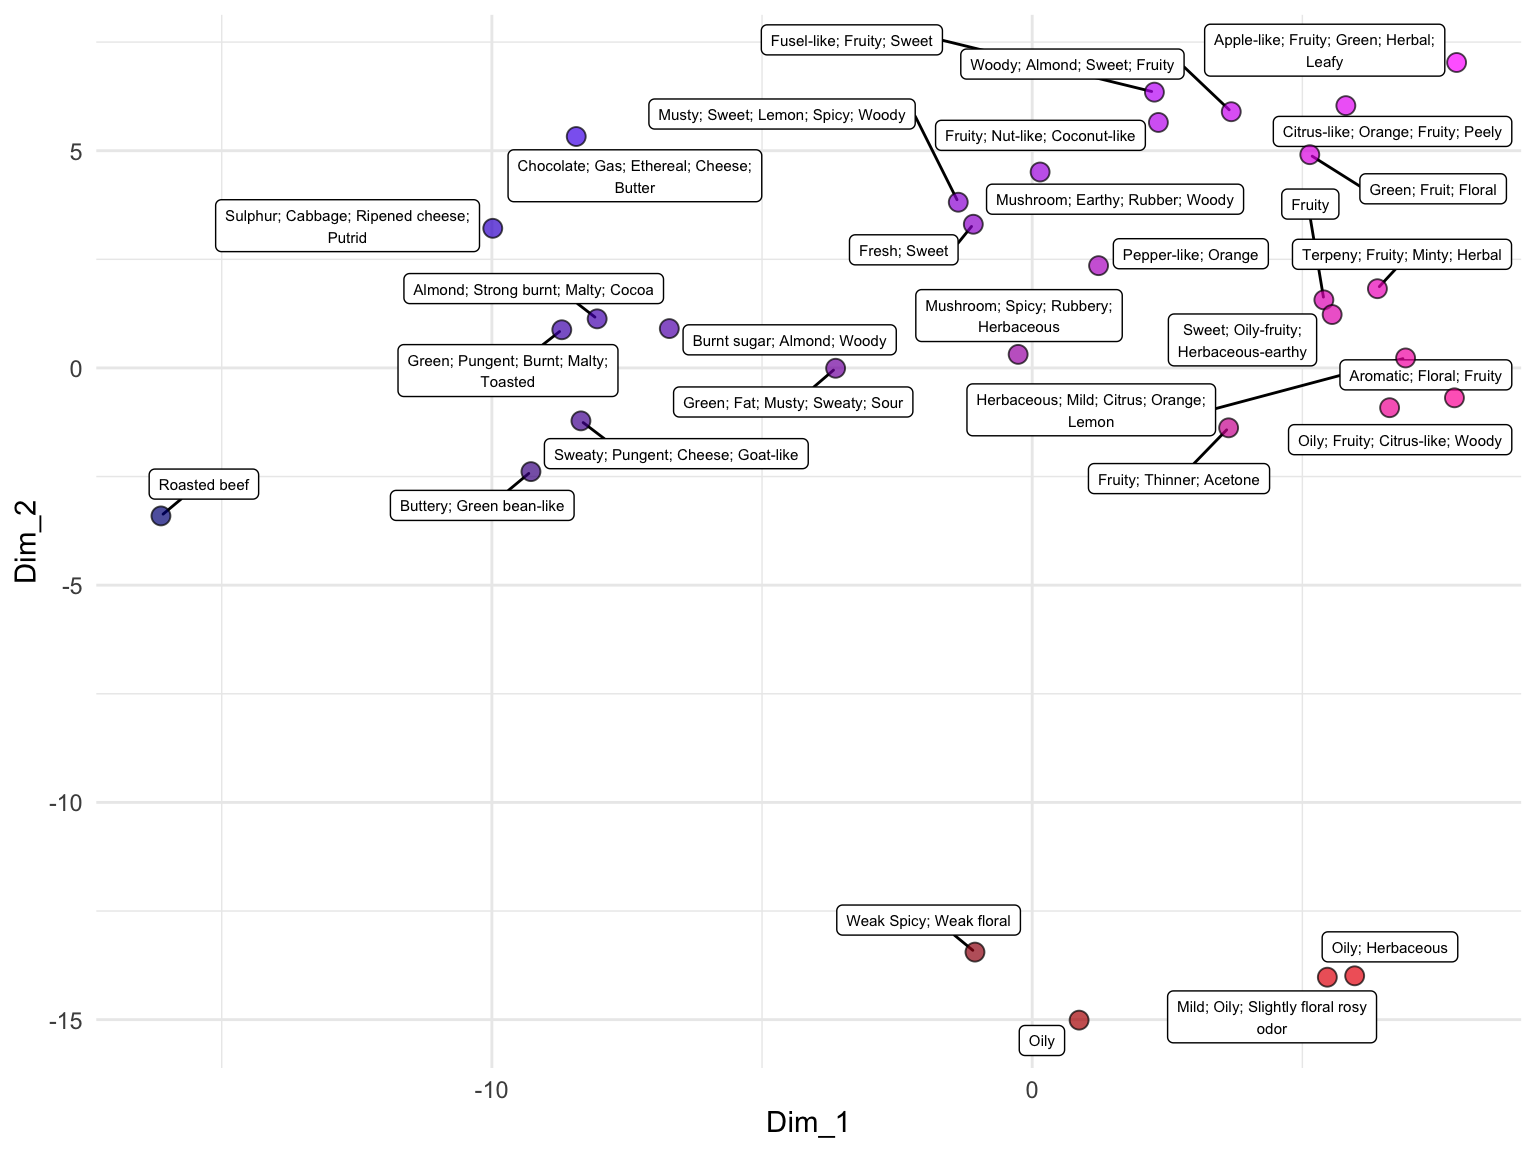
generative models
Embedding models convert language into numbers so that we can measure similarity. An extension of that same process can be used to create a generative language model, which uses embedding under the hood to generate new text when given instructions. The generateText() function provided by the source() command sends text to the course generation endpoint and returns a new column of model responses alongside the input data. It takes a column with prompts (the prompt_column, which contains the text to be processed) and, optionally, a column with system messages that steer the model’s behavior (system_column, the instructions the model should follow when processing the input text). Each row is sent as a chat conversation: the system message sets the role, the prompt becomes the user message, and the model returns a reply.
In the example below, we ask the model to summarize each abstract with three comma-separated tags. We first add a system message to each row that defines the model’s role. We then call generateText(), passing the abstract column as the prompt. As with embedText(), there is no key in the code. The class token from the .Renviron file authenticates the request. Finally, we select the title and the generated tags to see the results.
Note that generation is much slower and much more expensive than embedding: each row is a separate request to a large model. Keep the number of rows small while experimenting.
search_results$system <- paste(
  "You are a scientific literature classification expert.",
  "Your job is to generate three comma-separated tags for abstracts that you are given."
)

search_results <- generateText(
  df = search_results,
  prompt_column = "abstract",
  system_column = "system"
)

select(search_results, title, generation)
## # A tibble: 12 × 2
##    title                                          generation
##    <chr>                                          <chr>
##  1 Ginsenosides in Panax genus and their biosynt… Ginsenosi…
##  2 β-Amyrin synthase from Conyza blinii expresse… Oxidosqua…
##  3 [Cloning and bioinformatics analysis of β-amy… Dipsacus …
##  4 Friedelin in Maytenus ilicifolia Is Produced … friedelin…
##  5 Genome Mining and Gene Expression Reveal Mayt… maytansin…
##  6 The Methionine 549 and Leucine 552 Residues o… Friedelin…
##  7 Current status and prospects of herbicide-res… herbicide…
##  8 Sorghum (Sorghum bicolor).                     Sorghum t…
##  9 Potential food applications of sorghum (Sorgh… sorghum, …
## 10 Regulatory mechanisms underlying cuticular wa… Plant cut…
## 11 Cuticular wax in wheat: biosynthesis, genetic… Plant cut…
## 12 Update on Cuticular Wax Biosynthesis and Its … plant cut…
chapter summary
Download this summary as a one-page PDF
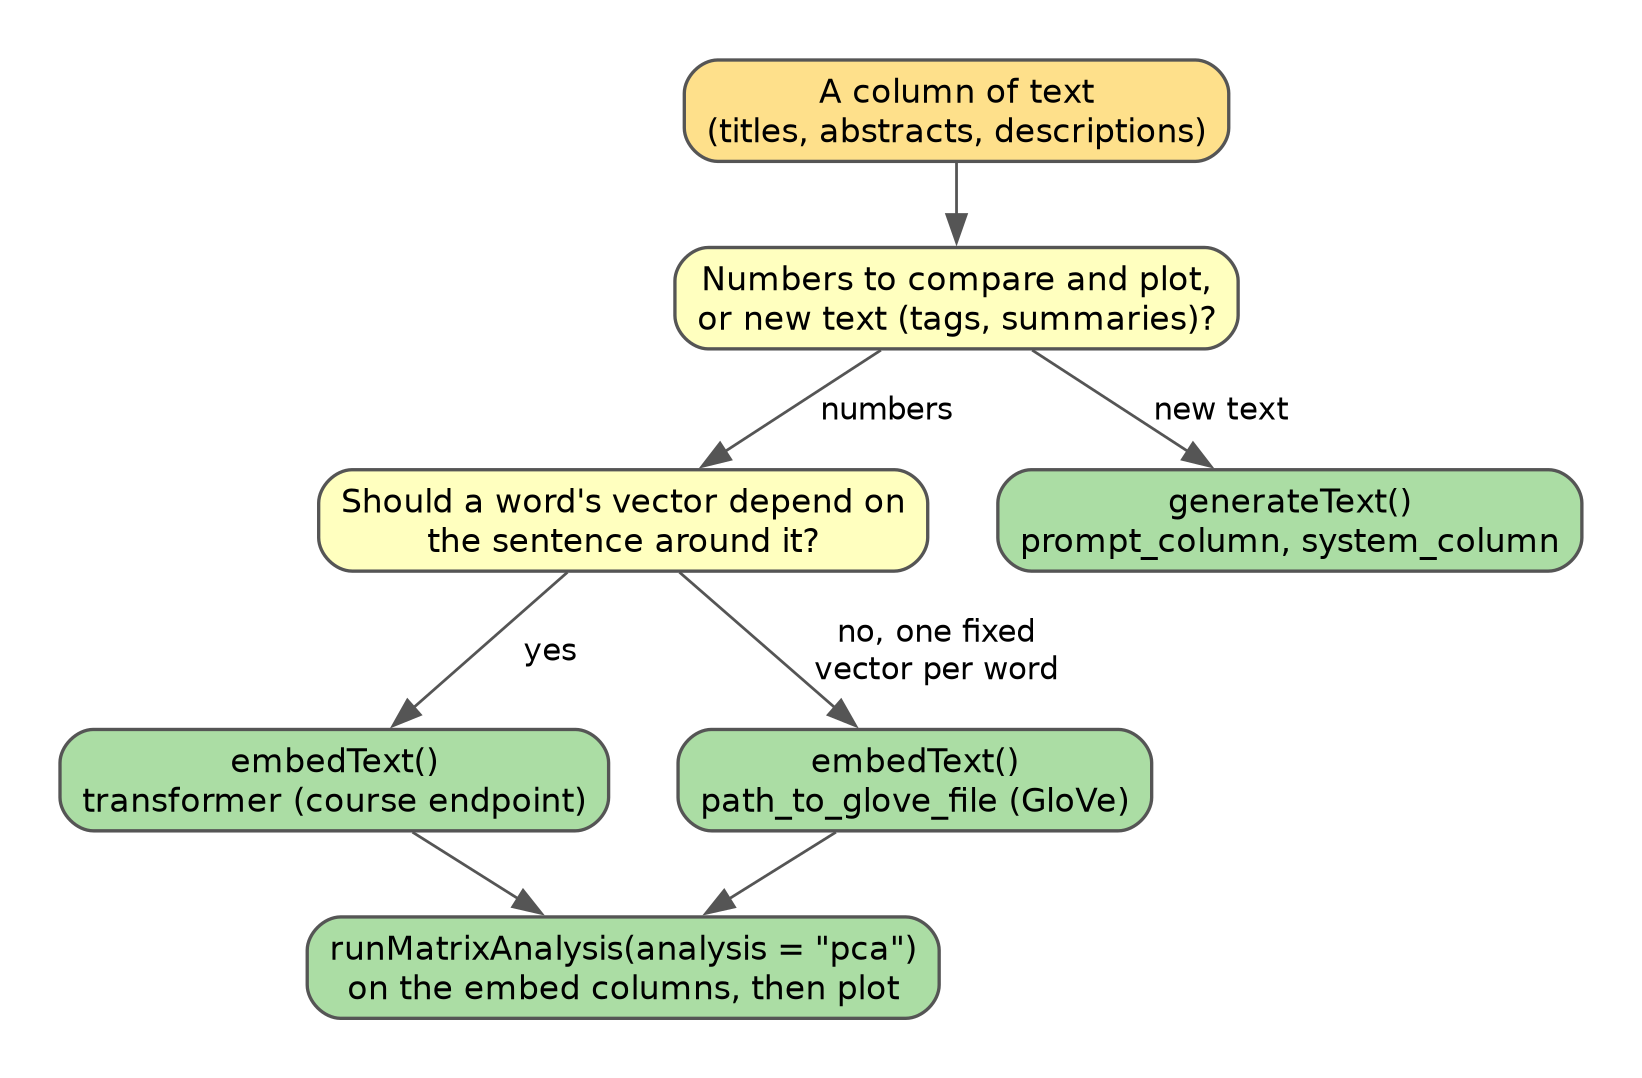
Choosing a language model approach. This decision flowchart starts from what is wanted back from a column of text and ends at the function, and the argument that sets it up, used in this chapter. Yellow boxes are questions about the task and green boxes are the recommended function calls.
Language models turn text into numbers. An embedding model converts each title, abstract or description into a vector (384 numbers for the course transformer model), and texts with similar meanings get similar vectors, so familiar tools such as PCA can show which ones group together. The two embedding methods differ in how they treat context: GloVe gives every word one fixed vector and averages the word vectors over a sentence, whereas a transformer adjusts each word’s vector to fit the sentence around it. A generative model builds on the same machinery to write new text in response to a prompt and a system message, and it is much slower and more expensive than embedding because each row is a separate request to a large model. Keys and tokens live in .Renviron and are read with Sys.getenv(), never typed into code.
| Function | What it is for | Arguments varied in this chapter |
|---|---|---|
searchPubMed() |
retrieve PubMed records (title, abstract, journal) for a set of search terms |
search_terms, pubmed_api_key = Sys.getenv("PUBMED_TOKEN"), retmax_per_term, sort ("relevance" or "date") |
embedText(), transformer |
contextual embeddings from the course endpoint (BAAI/bge-small-en-v1.5, 384 columns) |
df, column_name (the class token is picked up from .Renviron) |
embedText(), GloVe |
one fixed vector per word, averaged over each sentence |
column_name, path_to_glove_file = Sys.getenv("GLOVE_FILE")
|
runMatrixAnalysis() |
PCA on the embedding columns to see which texts group together |
analysis = "pca", columns_w_values_for_single_analyte (the columns found by grep("embed", ...)), columns_w_sample_ID_info
|
generateText() |
new text (here, three tags per abstract) from the course generation endpoint |
df, prompt_column, system_column
|
further reading
creating knowledge graphs with LLMs. This blog post explains how to create knowledge graphs from text using OpenAI functions combined with LangChain and Neo4j. It highlights how large language models (LLMs) have made information extraction more accessible, providing step-by-step instructions for setting up a pipeline to extract structured information and construct a graph from unstructured data.
creating RAG systems with LLMs. This article provides a technical overview of implementing complex Retrieval Augmented Generation (RAG) systems, focusing on key concepts like chunking, query augmentation, document hierarchies, and knowledge graphs. It highlights the challenges in data retrieval, multi-hop reasoning, and query planning, while also discussing opportunities to improve RAG infrastructure for more accurate and faster information extraction.